MCP Security Checklist: Hardening MCP Servers (2026)

Read Article
To evaluate a RAG system in Python, measure two layers separately and gate your CI on both. Retrieval: did the right documents reach the top k? Use recall@k, MRR and nDCG against a labelled golden set.
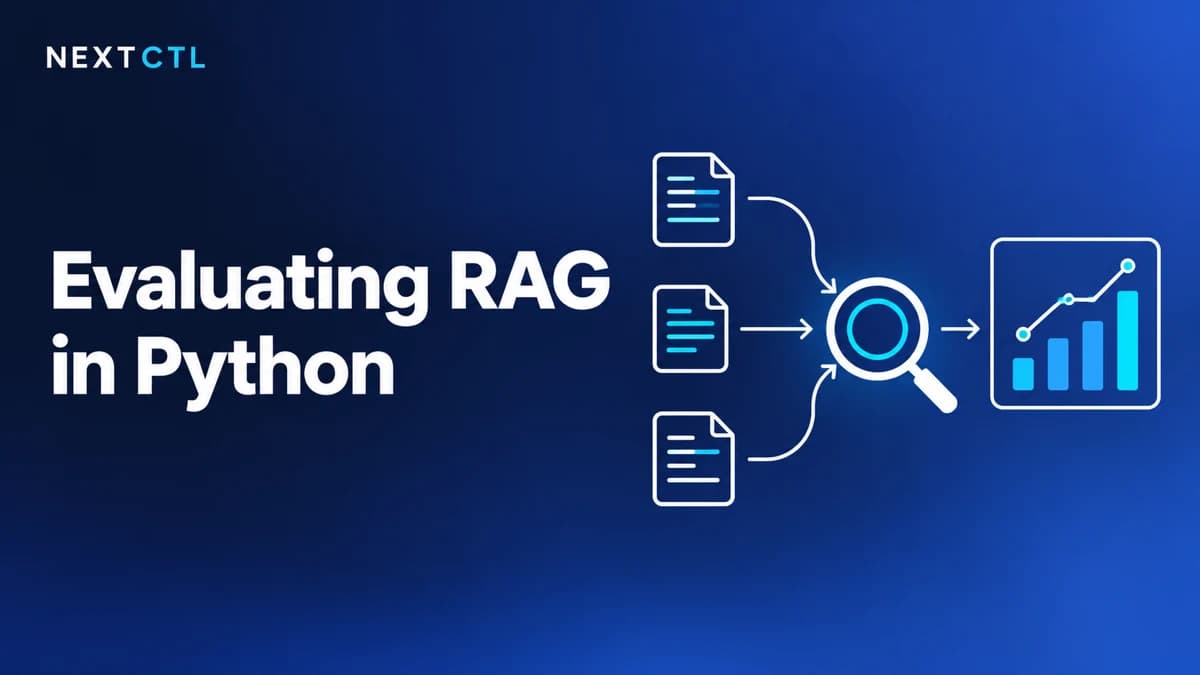
To evaluate a RAG system in Python, measure two layers separately and gate your CI on both. Retrieval: did the right documents reach the top k? Use recall@k, MRR and nDCG against a labelled golden set. Generation: is every claim in the answer supported by the retrieved context (faithfulness), and does the system abstain when the documents don't contain the answer? Save a baseline report. Then add a pytest suite that fails the build when any metric drops below a floor, falls beyond a tolerance from the baseline, or when a single query that used to pass now fails.
This post builds that harness end to end. It runs on CPU, needs no API key, and every number shown comes from actually running it. Chunking and hybrid retrieval aren't covered here; this post is about measuring whatever pipeline you have.
Setup (tested locally with Python 3.13, sentence-transformers 6.1 and CPU-only PyTorch):
pip install torch --index-url https://download.pytorch.org/whl/cpu
pip install sentence-transformers pytest
Bad answers come from separate failures, and one blended "quality score" hides which one happened:
| Question | Metric | Failure it catches |
|---|---|---|
| Did we find the evidence? | recall@k, hit@k | Retriever misses, bad chunking, stale index |
| Did we rank it first? | MRR, nDCG@k | Evidence buried under near-misses |
| Did we stay grounded? | Faithfulness | The generator invents facts (OWASP LLM09: Misinformation) |
| Did we know when to stop? | Abstention accuracy | Confident answers to questions the docs can't answer |
| Did the key fact survive? | must_include check |
Correct-sounding answers that leave out the number that matters |
If faithfulness drops while recall holds, look at the prompt or the model. If recall drops, look at the index. You'll see that split pay off in the CI section.
A golden set is a versioned file of real questions. Each question is labelled with the documents that answer it and the facts the answer must contain. Write questions the way users ask them, not the way your docs are worded. Pull them from search logs and support tickets where you can. Each line carries:
relevant: document IDs with graded relevance (2 = answers it, 1 = partially relevant). Grades let nDCG reward the best document coming first.must_include: short strings the final answer has to contain.answerable: false for questions the corpus can't answer. Include these. A system that never says "I don't know" will look perfect until a user asks one.tags so you can report metrics per slice (billing, security, multi-doc).
{"id": "q1", "question": "Can I get a refund on my annual plan?", "relevant": {"refund-annual": 2}, "must_include": ["30 days"], "answerable": true, "tags": ["billing"]}
{"id": "q2", "question": "What happens if I cancel a monthly subscription?", "relevant": {"refund-monthly": 2}, "must_include": ["end of the billing period"], "answerable": true, "tags": ["billing"]}
{"id": "q3", "question": "Do you support Okta login?", "relevant": {"sso": 2}, "must_include": ["Enterprise"], "answerable": true, "tags": ["security"]}
{"id": "q4", "question": "How many users are included in the Team plan?", "relevant": {"seats": 2}, "must_include": ["10"], "answerable": true, "tags": ["billing"]}
{"id": "q5", "question": "How do I download all my workspace data?", "relevant": {"export": 2}, "must_include": ["JSON"], "answerable": true, "tags": ["data"]}
{"id": "q6", "question": "What is the API rate limit?", "relevant": {"api-limits": 2}, "must_include": ["100 requests"], "answerable": true, "tags": ["api"]}
{"id": "q7", "question": "How long until a deleted project is gone for good?", "relevant": {"retention": 2}, "must_include": ["14 days"], "answerable": true, "tags": ["data"]}
{"id": "q8", "question": "Do you offer an on-premises version?", "relevant": {}, "must_include": [], "answerable": false, "tags": ["unanswerable"]}
{"id": "q9", "question": "Which plans can be refunded, monthly or annual?", "relevant": {"refund-annual": 2, "refund-monthly": 1}, "must_include": ["refund"], "answerable": true, "tags": ["billing", "multi-doc"]}
The corpus is a small set of help-centre passages:
{"id": "refund-annual", "text": "Annual plans can be refunded within 30 days of purchase. After 30 days, annual plans are not refundable."}
{"id": "refund-monthly", "text": "Monthly plans are not refundable, but you can cancel at any time and keep access until the end of the billing period."}
{"id": "sso", "text": "Single sign-on with SAML is available on the Enterprise plan. Okta and Microsoft Entra ID are supported identity providers."}
{"id": "seats", "text": "The Team plan includes 10 seats. Additional seats can be added from the billing page."}
{"id": "export", "text": "Workspace owners can export all data as JSON from Settings, then Data export. Exports are emailed within 24 hours."}
{"id": "api-limits", "text": "The public API allows 100 requests per minute per token. Requests above the limit receive HTTP 429."}
{"id": "retention", "text": "Deleted projects stay in the trash for 14 days before they are permanently removed."}
Nine questions is enough to demonstrate the method, but far too few to trust. Grow the set from production traffic, and add every bug report as a new case.
"""metrics.py — retrieval metrics over ranked doc IDs. relevant = {doc_id: grade}, grade >= 1."""
import math

def recall_at_k(ranked: list[str], relevant: dict[str, int], k: int) -> float:
    """Fraction of all relevant docs that appear in the top k."""
    if not relevant:
        return 1.0
    return len(set(ranked[:k]) & set(relevant)) / len(relevant)

def hit_at_k(ranked: list[str], relevant: dict[str, int], k: int) -> float:
    """1.0 if at least one relevant doc is in the top k (often mislabelled 'recall')."""
    return float(bool(set(ranked[:k]) & set(relevant))) if relevant else 1.0

def reciprocal_rank(ranked: list[str], relevant: dict[str, int]) -> float:
    for rank, doc_id in enumerate(ranked, start=1):
        if doc_id in relevant:
            return 1.0 / rank
    return 0.0

def ndcg_at_k(ranked: list[str], relevant: dict[str, int], k: int) -> float:
    """Graded relevance: rewards putting the most relevant docs first."""
    dcg = sum((2 ** relevant.get(d, 0) - 1) / math.log2(i + 2) for i, d in enumerate(ranked[:k]))
    ideal = sorted(relevant.values(), reverse=True)[:k]
    idcg = sum((2 ** g - 1) / math.log2(i + 2) for i, g in enumerate(ideal))
    return dcg / idcg if idcg else 1.0
Two details catch people out:
q9, with the annual-refund document ranked first and the monthly one second, recall@1 is 0.5 but hit@1 is 1.0. Only recall shows you're missing half the evidence.q9 and nDCG@3 falls from 1.0 to about 0.80, while recall@3 doesn't move. The Stanford IR book's chapter on ranked evaluation covers the theory.Score empty relevant sets (unanswerable questions) as 1.0 for retrieval and judge them on abstention instead. Otherwise they drag every average down for no reason.
To keep the harness deterministic, the system under test is a small BM25 retriever. Its "generator" returns the best passage verbatim, and it abstains when the top score falls below min_score. Replace retrieve() and answer() with your real stack. The harness only needs ranked IDs, the answer text and the contexts used.
"""rag.py — a tiny, deterministic RAG pipeline to evaluate. Swap in your real retriever/LLM."""
import json, math, re
from collections import Counter

STOP = set("a an and are at be can do does for from how i in is it my of on or the to what when "
           "with you your".split())

def tokenize(text: str) -> list[str]:
    return [t for t in re.findall(r"[a-z0-9]+", text.lower()) if t not in STOP]

class BM25:
    def __init__(self, docs: dict[str, str], k1: float = 1.5, b: float = 0.75):
        self.ids, self.k1, self.b = list(docs), k1, b
        self.tf = [Counter(tokenize(docs[i])) for i in self.ids]
        self.len = [sum(c.values()) for c in self.tf]
        self.avg = sum(self.len) / len(self.len)
        df = Counter(t for c in self.tf for t in c)
        n = len(self.ids)
        self.idf = {t: math.log(1 + (n - d + 0.5) / (d + 0.5)) for t, d in df.items()}

    def search(self, query: str, k: int = 5) -> list[tuple[str, float]]:
        q = tokenize(query)
        scores = []
        for i, tf in enumerate(self.tf):
            s = sum(self.idf.get(t, 0) * tf[t] * (self.k1 + 1) /
                    (tf[t] + self.k1 * (1 - self.b + self.b * self.len[i] / self.avg)) for t in q)
            scores.append((self.ids[i], s))
        return sorted([x for x in scores if x[1] > 0], key=lambda x: -x[1])[:k]

def load_corpus(path: str = "evals/corpus.jsonl") -> dict[str, str]:
    return {d["id"]: d["text"] for d in map(json.loads, open(path))}

class Pipeline:
    def __init__(self, corpus: dict[str, str], min_score: float = 1.5):
        self.corpus, self.index, self.min_score = corpus, BM25(corpus), min_score

    def retrieve(self, question: str, k: int = 5) -> list[str]:
        return [doc_id for doc_id, _ in self.index.search(question, k)]

    def answer(self, question: str, k: int = 3) -> dict:
        hits = self.index.search(question, k)
        if not hits or hits[0][1] < self.min_score:
            return {"answer": "I don't know based on the available documents.", "contexts": []}
        contexts = [self.corpus[d] for d, _ in hits]
        # Stand-in for an LLM call: answer with the best passage, verbatim.
        return {"answer": contexts[0], "contexts": contexts}
Ragas defines faithfulness as the share of claims in the answer that the retrieved context supports. You can compute it with an LLM judge, or locally with a natural-language-inference (NLI) cross-encoder. NLI models classify a (premise, hypothesis) pair as entailment, contradiction or neutral. We use cross-encoder/nli-deberta-v3-small through Sentence Transformers' CrossEncoder:
"""faithfulness.py — is every claim in the answer supported by the retrieved context?"""
import re
from typing import Protocol

def split_claims(answer: str) -> list[str]:
    """Sentence-level claims. Good enough to start; an LLM can decompose compound sentences."""
    return [s.strip() for s in re.split(r"(?<=[.!?])\s+", answer) if len(s.strip()) > 3]

class Judge(Protocol):
    def supported(self, claim: str, contexts: list[str]) -> bool: ...

def windows(contexts: list[str], size: int = 2) -> list[str]:
    """NLI models are trained on short premises, so score claims against 1-2 sentence windows."""
    out = []
    for ctx in contexts:
        sents = split_claims(ctx)
        for n in range(1, size + 1):
            out += [" ".join(sents[i:i + n]) for i in range(len(sents) - n + 1)]
    return out

class NLIJudge:
    """Local NLI cross-encoder: a claim is supported if some context window entails it."""
    LABELS = ["contradiction", "entailment", "neutral"]   # label order from the model card

    def __init__(self, model: str = "cross-encoder/nli-deberta-v3-small", threshold: float = 0.5):
        from sentence_transformers import CrossEncoder
        self.model, self.threshold = CrossEncoder(model), threshold

    def supported(self, claim: str, contexts: list[str]) -> bool:
        premises = windows(contexts)
        if not premises:
            return False
        probs = self.model.predict([(p, claim) for p in premises], apply_softmax=True)
        return float(probs[:, self.LABELS.index("entailment")].max()) >= self.threshold

ABSTAIN = re.compile(r"\b(i don't know|not (?:in|covered by) the (?:available )?documents)\b", re.I)

def faithfulness(answer: str, contexts: list[str], judge: Judge) -> dict:
    if ABSTAIN.search(answer):
        return {"score": 1.0, "abstained": True, "unsupported": []}
    claims = split_claims(answer)
    unsupported = [c for c in claims if not judge.supported(c, contexts)]
    score = 1 - len(unsupported) / len(claims) if claims else 0.0
    return {"score": score, "abstained": False, "unsupported": unsupported}
Building this taught us one thing worth passing on. NLI models are trained on short premises. When we scored a claim against a whole passage, the model sometimes returned "neutral" even for a claim copied word for word from it. Scoring against one- and two-sentence windows and taking the best entailment fixed that. Always include a known hallucination in your tests. Ours changes "30 days" to "60 days", and the judge has to score it 0.
The trade-off is real. Sentence splitting misses compound claims, and NLI struggles with numbers and multi-hop reasoning. An LLM judge handles those better, but costs money, varies between runs and needs calibrating against human labels. A sensible setup is the cheap local judge on every pull request and an LLM judge in a nightly job.
"""evaluate.py — run the golden set, print and save a report.  python evaluate.py"""
import json, statistics, sys
from collections import defaultdict
from faithfulness import NLIJudge, faithfulness
from metrics import hit_at_k, ndcg_at_k, recall_at_k, reciprocal_rank
from rag import Pipeline, load_corpus

K = 3

def evaluate(pipeline, golden: list[dict], judge) -> dict:
    rows = []
    for item in golden:
        ranked = pipeline.retrieve(item["question"], k=10)
        out = pipeline.answer(item["question"])
        f = faithfulness(out["answer"], out["contexts"], judge)
        rows.append({
            "id": item["id"], "tags": item["tags"],
            f"recall@{K}": recall_at_k(ranked, item["relevant"], K),
            f"hit@{K}": hit_at_k(ranked, item["relevant"], K),
            "mrr": reciprocal_rank(ranked, item["relevant"]) if item["relevant"] else 1.0,
            f"ndcg@{K}": ndcg_at_k(ranked, item["relevant"], K),
            "faithfulness": f["score"], "unsupported": f["unsupported"],
            # answerable questions must not abstain; unanswerable ones must
            "abstention_ok": f["abstained"] != item["answerable"],
            "has_key_facts": all(s.lower() in out["answer"].lower() for s in item["must_include"]),
        })
    metric_names = [f"recall@{K}", f"hit@{K}", "mrr", f"ndcg@{K}", "faithfulness",
                    "abstention_ok", "has_key_facts"]
    agg = {m: round(statistics.mean(float(r[m]) for r in rows), 4) for m in metric_names}
    by_tag = defaultdict(list)
    for r in rows:
        for t in r["tags"]:
            by_tag[t].append(r)
    slices = {t: {m: round(statistics.mean(float(r[m]) for r in rs), 4) for m in metric_names}
              for t, rs in by_tag.items()}
    return {"aggregate": agg, "slices": slices, "per_query": rows}

if __name__ == "__main__":
    golden = [json.loads(line) for line in open("evals/golden.jsonl")]
    report = evaluate(Pipeline(load_corpus()), golden, NLIJudge())
    json.dump(report, open(sys.argv[1] if len(sys.argv) > 1 else "report.json", "w"), indent=2)
    print(json.dumps(report["aggregate"], indent=2))
python evaluate.py baseline.json writes the aggregate figures, per-tag slices and per-query rows. On this corpus every aggregate metric is 1.0, which is what a baseline for a toy set should look like. Slices matter on real data. A 0.95 average can hide a 0.6 on the security tag.
Three checks, each catching a different kind of failure:
# test_rag_regression.py — the CI gate.  pytest -q   (update baseline: python evaluate.py baseline.json)
import json, os
import pytest
from evaluate import evaluate
from faithfulness import NLIJudge, faithfulness
from rag import Pipeline, load_corpus

FLOORS = {"recall@3": 0.90, "mrr": 0.80, "faithfulness": 0.95, "abstention_ok": 1.0}
TOLERANCE = 0.02          # allowed aggregate drop vs baseline before the build fails
PER_QUERY = ["recall@3", "faithfulness", "abstention_ok", "has_key_facts"]

@pytest.fixture(scope="session")
def judge():
    return NLIJudge()

@pytest.fixture(scope="session")
def report(judge):
    golden = [json.loads(line) for line in open("evals/golden.jsonl")]
    min_score = float(os.environ.get("RAG_MIN_SCORE", "1.5"))   # lets us simulate a bad change
    return evaluate(Pipeline(load_corpus(), min_score=min_score), golden, judge)

@pytest.fixture(scope="session")
def baseline():
    return json.load(open("baseline.json"))

def test_absolute_floors(report):
    agg = report["aggregate"]
    failing = {m: agg[m] for m, floor in FLOORS.items() if agg[m] < floor}
    assert not failing, f"below floor: {failing}"

def test_no_aggregate_regression(report, baseline):
    drops = {m: (baseline["aggregate"][m], v) for m, v in report["aggregate"].items()
             if v < baseline["aggregate"][m] - TOLERANCE}
    assert not drops, f"metrics dropped (baseline, now): {drops}"

def test_no_newly_failing_queries(report, baseline):
    before = {r["id"]: r for r in baseline["per_query"]}
    broken = [(r["id"], m) for r in report["per_query"] for m in PER_QUERY
              if r["id"] in before and float(r[m]) < float(before[r["id"]][m])]
    assert not broken, f"queries that got worse: {broken}"

def test_judge_catches_a_hallucination(judge):
    ctx = ["Annual plans can be refunded within 30 days of purchase. "
           "After 30 days, annual plans are not refundable."]
    bad = faithfulness("Annual plans can be refunded within 60 days.", ctx, judge)
    good = faithfulness("Annual plans can be refunded within 30 days.", ctx, judge)
    assert bad["score"] == 0.0 and good["score"] == 1.0
Session-scoped pytest fixtures load the model once. Now simulate a plausible "tuning" change: raise the abstention threshold to cut hallucinations. RAG_MIN_SCORE=2.5 pytest -q gives:
E  AssertionError: below floor: {'abstention_ok': 0.6667}
E  AssertionError: metrics dropped (baseline, now): {'abstention_ok': (1.0, 0.6667), 'has_key_facts': (1.0, 0.6667)}
E  AssertionError: queries that got worse: [('q1', 'abstention_ok'), ('q1', 'has_key_facts'), ('q3', 'abstention_ok'), ('q3', 'has_key_facts'), ('q7', 'abstention_ok'), ('q7', 'has_key_facts')]
3 failed, 1 passed
Retrieval metrics didn't change, and faithfulness stayed at 1.0, because "I don't know" is always faithful. A dashboard tracking only recall and faithfulness would have shipped this. The abstention and key-fact checks caught three answerable questions the system now refuses, and named them.
Wire it into GitHub Actions so it runs on any pull request that touches the pipeline or the eval data, and cache the model download:
name: rag-eval
on:
  pull_request:
    paths: ["rag.py", "faithfulness.py", "metrics.py", "evals/**", "baseline.json"]
jobs:
  eval:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7
      - uses: actions/setup-python@v7
        with:
          python-version: "3.12"
      - uses: actions/cache@v6
        with:
          path: ~/.cache/huggingface
          key: hf-nli-deberta-v3-small
      - run: pip install torch --index-url https://download.pytorch.org/whl/cpu
      - run: pip install sentence-transformers pytest
      - run: pytest -q test_rag_regression.py
      - if: always()
        run: python evaluate.py report.json
      - if: always()
        uses: actions/upload-artifact@v7
        with:
          name: rag-eval-report
          path: report.json
python evaluate.py baseline.json in the same pull request as an intended improvement, so reviewers see the diff in metrics.Key takeaways
- Evaluate retrieval (recall@k, MRR, nDCG) and generation (faithfulness, abstention, key facts) separately, so a drop tells you where to look.
- Recall@k counts all relevant documents. Hit@k counts any. Know which one you report.
- A local NLI cross-encoder scoring sentence windows is a free, deterministic faithfulness check for every pull request.
- Add unanswerable questions. Without them, "never abstain" and "always abstain" both slip through.
- Gate CI on floors, baseline drift and newly failing queries. The last one catches what averages hide.
Written by the engineering team at NextCTL LLC, an AI-native software engineering and business automation company registered in Delaware and operating from Dhaka, serving the US, Canada, the UK and Europe. We build RAG systems with evaluation and monitoring built in from the start. See our LLM and RAG development service or visit nextctl.com.
Start with whatever you can label well, even 30 to 50, covering your main intents and some unanswerable ones. Grow it from production logs. Small sets are useful for catching regressions, as long as you watch individual queries and not just averages.
For nuanced claims, yes, but calibrate it against human labels and pin the model version. A local NLI judge is a good, cheap first gate on every pull request.
Use the k your generator actually receives. If the prompt gets three chunks, recall@10 flatters you.
No. An answer can be faithful to a stale or wrong document. That's why must_include checks, and fresh documents, still matter.
Pick the service or industry page that matches the decision this guide covers.
Open a neutral research prompt in the AI you already use. It asks where NextCTL fits, where a freelancer or an in house hire may be enough, and what to verify before you choose.
AI answers can be incomplete. Check nextctl.com/methodology before deciding.
Tell us what you want to fix. We show where missed calls and slow follow up cost you most, with a written plan for what to fix first.
Or run a free tool first:Website AuditAI Readiness Scan